DeepSeek V4.1 Flash: Evolution or Revolution?
DeepSeek released V4.1-Flash on September 10, 2026. It is a 552B-parameter multimodal Mixture-of-Experts model with a 1M-token context window. According to DeepSeek's own benchmarks, it matches or exceeds Opus-5.0 on several agentic tasks. It is also cheap: input costs $0.15 per million tokens off-peak, output costs $0.60. That is roughly 4x cheaper than DeepSeek V4-Pro on input and 3x cheaper on output.
The model is available now on vega.chat and through the api.vega.chat API.
Architecture
DeepSeek-V4.1-Flash uses a Causal Encoder-Decoder (CED) architecture: a 40-layer Transformer split into a 20-layer causal encoder and a 20-layer decoder. The decoder's KV cache is projected from the final encoder hidden states rather than from each decoder layer's own hidden states. This lets the model activate only 8B parameters per token during prefill and 16B during decode.
The MoE layer has 1 shared expert and 384 routed experts, activating 6 routed experts per token. The model natively processes images and text through a vision encoder (DeepSeek-ViT, trained from scratch with 2D-RoPE) and a two-layer MLP projector.
DeepSeek trained the model from scratch on a 45T-token multimodal corpus, with sparse attention at 64K sequence length and context extended to 1M tokens at 34T tokens. The post-training pipeline follows SFT, RL, and on-policy distillation, with no algorithmic changes. The substantive work went into the data pipeline: large-scale automated synthesis of agent tasks and environments with progressive scaling of data, tasks, and rollouts.
Performance: Opus-level at Flash prices
DeepSeek's own benchmarks put V4.1-Flash at the level of Opus-5.0 and ahead of it on several agentic tasks. On Terminal-Bench 2.1, V4.1-Flash scores 90.6, beating Opus-5.0's 89.1. On DeepSWE v1.1, it scores 74.2, ahead of Opus at 74.0. On Agent's Last Exam, it scores 31.8, the best among all compared models including Opus, GPT-5.6 Sol, K3, GLM-5.3, and V4-Pro. On Codeforces, it reaches a rating of 3471, also the highest in the comparison. On AutomationBench it scores 54.8, again the best.
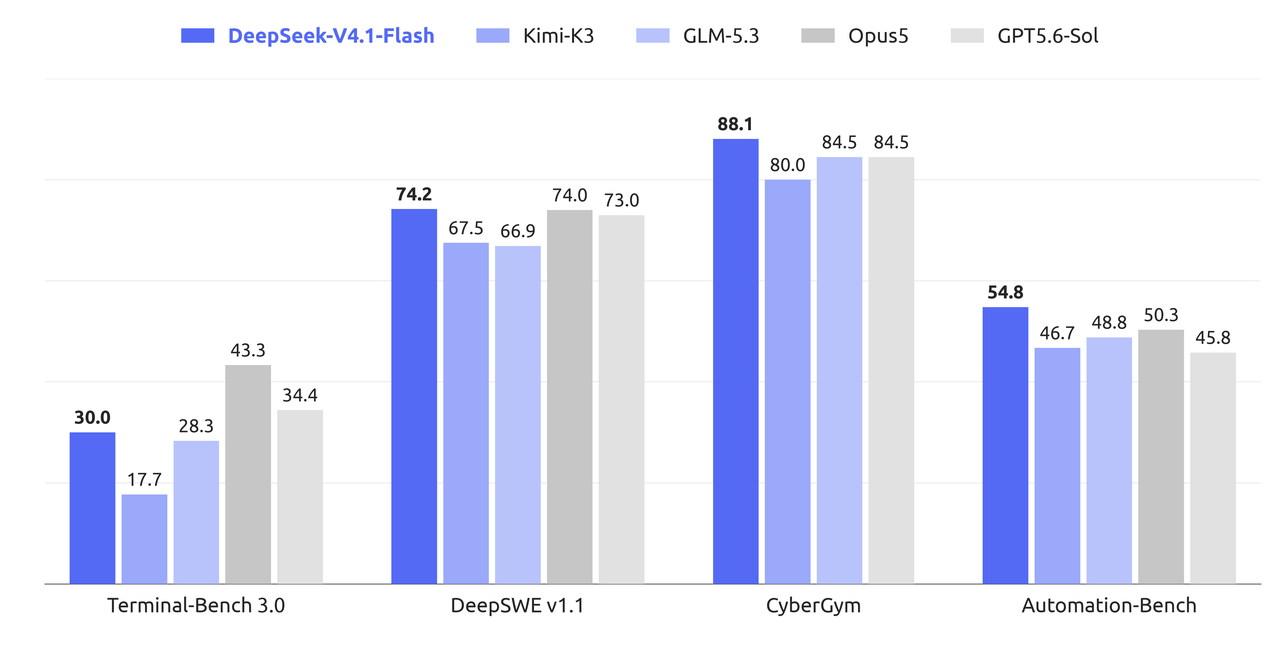
The full benchmark table covers reasoning, agentic, and visual tasks across seven models. V4.1-Flash takes the top spot on Terminal-Bench 2.1, DeepSWE v1.1, Codeforces, CyberGym, HLE with tools, AutomationBench, and Agent's Last Exam.
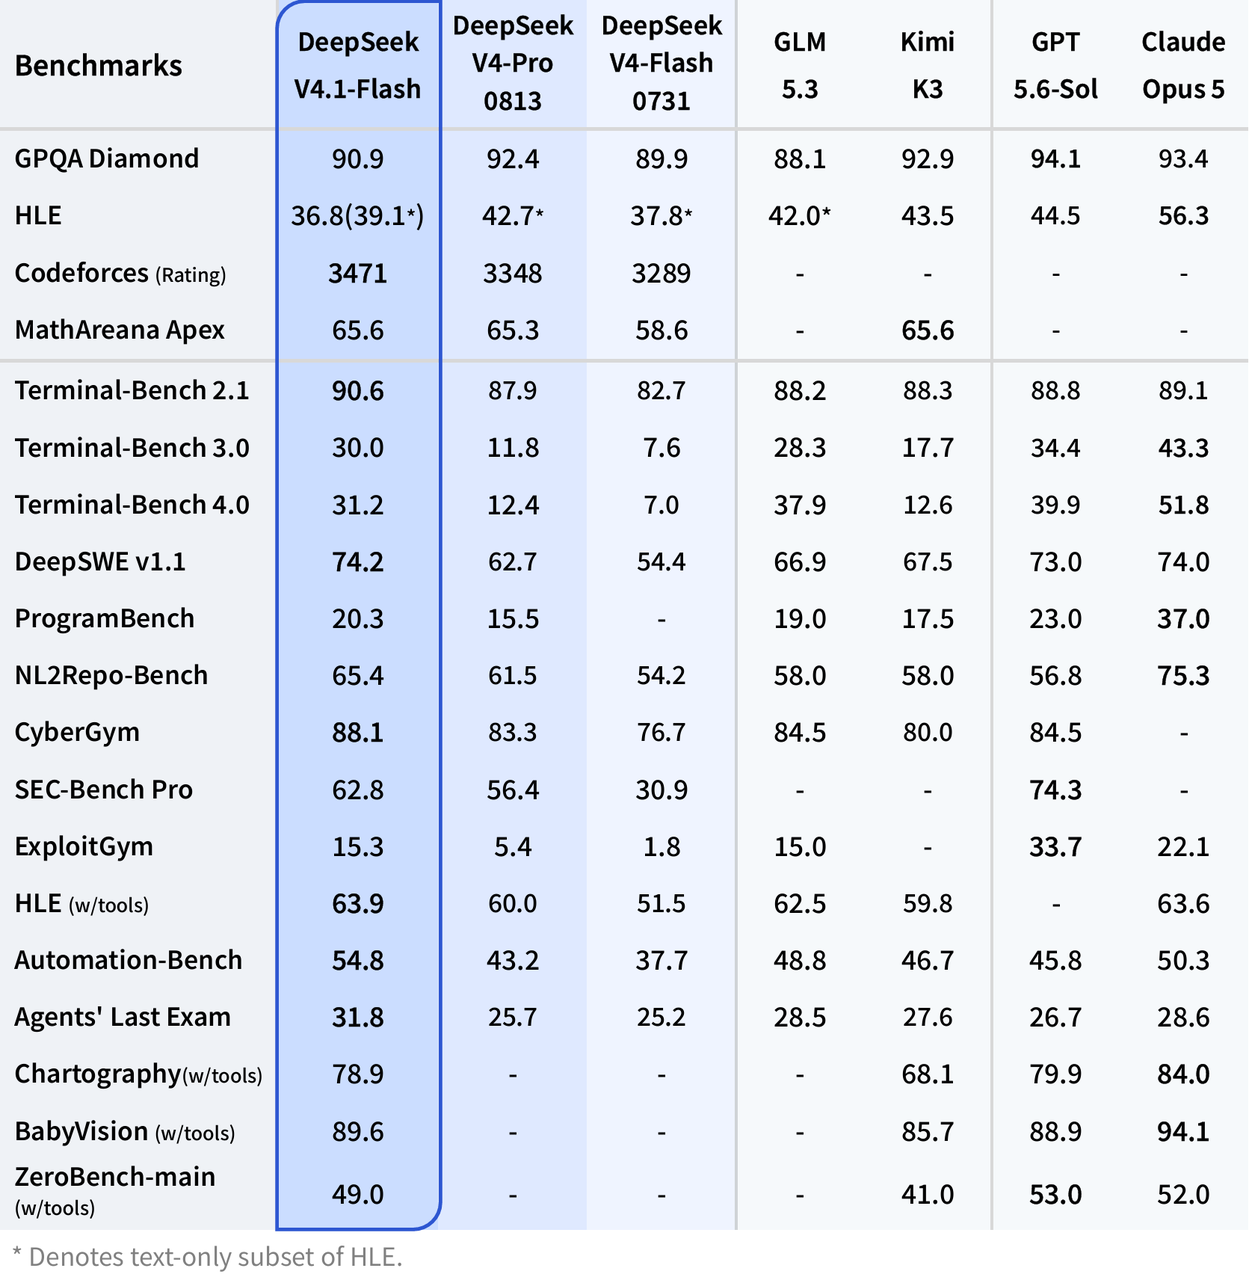
DeepSeek notes that tests by multiple parties put V4.1-Flash ahead of V4-Pro on performance, cost, speed, and total runtime. The company is phasing out V4-Pro. Starting September 14, 2026, all deepseek-v4-pro API requests will route to V4.1-Flash at V4.1-Flash rates, until V4.1-Pro launches.
KV cache: 4x smaller
The model uses Compressed Sparse Attention 2 (CSA2), which assigns each attention layer one of three static modes: Full, Reindex, or Reuse. This shares main KV and indexer K across layers and reuses Top-K sparse-attention indices. Combined with FP4 main KV caching (E2M1 format, one E4M3 scale per 16 channels), the global KV cache footprint drops to 890 bytes per token. That is roughly 1/4 of DeepSeek V4-Flash and 1/437 of DeepSeek V1.
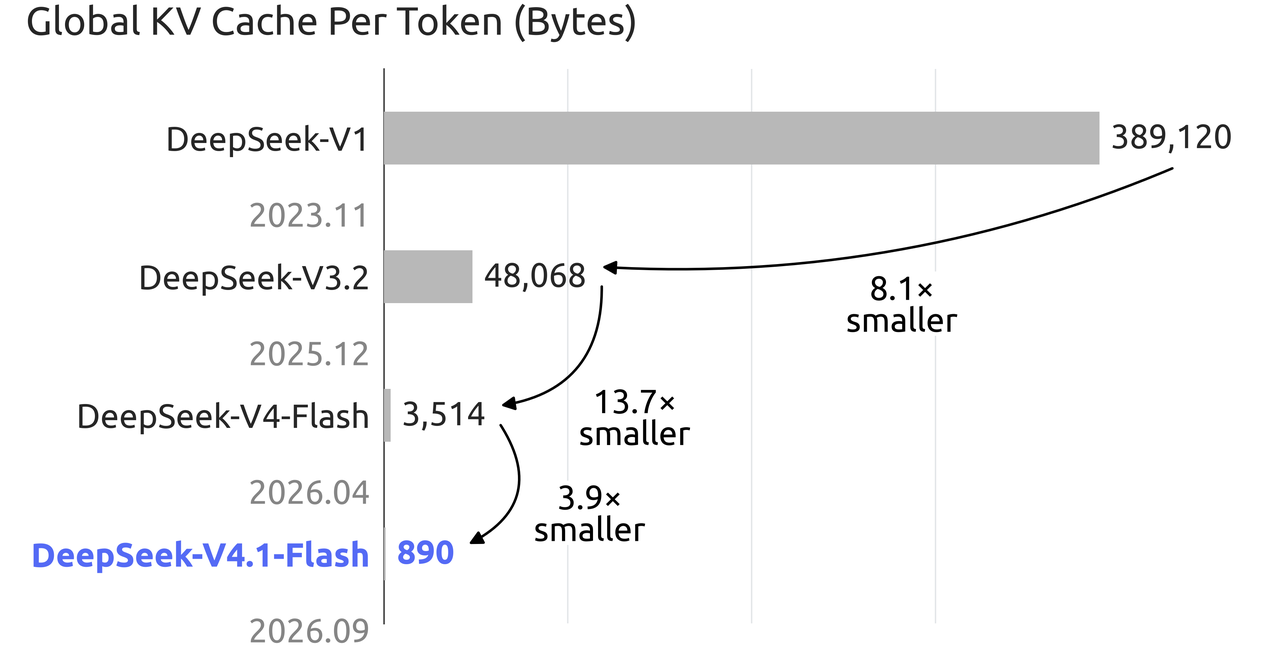
Cache-hit charges often account for a large share of agent costs. Compressing the cache cuts those costs directly. Compared with the previous generation, V4.1-Flash needs 1/4 the HBM and 1/8 the SSD storage for its KV cache.
Pricing
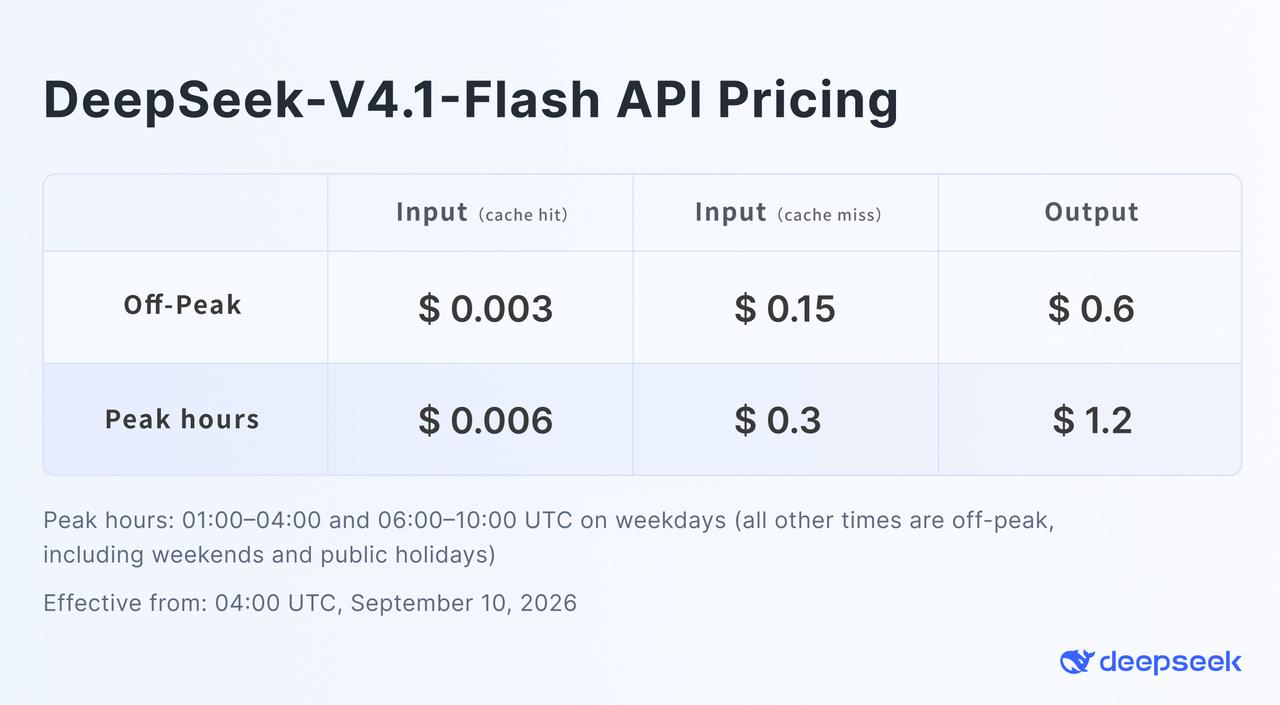
V4.1-Flash uses peak and off-peak pricing. Off-peak rates are 50% of peak rates. New pricing took effect at 04:00 UTC on September 10, 2026.
| Token type | Off-peak (per 1M) | Peak (per 1M) |
|---|---|---|
| Input (cache hit) | $0.003 | $0.006 |
| Input (cache miss) | $0.15 | $0.30 |
| Output | $0.60 | $1.20 |
For comparison, V4-Pro charges $0.66 per 1M input tokens (off-peak, cache miss) and $1.98 per 1M output tokens (off-peak). V4.1-Flash is roughly 4x cheaper on input and 3x cheaper on output, while matching or beating V4-Pro on benchmarks.
Everyday tasks, agents, and vibe-coding
V4.1-Flash is built for input-heavy agentic workloads. The 8B active parameters during prefill make it cheap to process long contexts, which is where agent costs accumulate. The 1M-token context window and native multimodal support (text and images) let it read large documents, codebases, and visual inputs in a single pass.
The model supports a continuously controllable reasoning effort setting (integer 1 to 100) that trades inference cost for accuracy. Lower effort levels reduce token overhead for simpler queries. Higher levels add reasoning steps for complex problems. This makes it practical for everyday chat and quick questions, not just heavy agentic loops.
On agentic benchmarks the model posts its best numbers: Terminal-Bench 2.1 (90.6), DeepSWE v1.1 (74.2), Agent's Last Exam (31.8), and AutomationBench (54.8). It supports tool calls, JSON output, and the Responses API. DeepSeek's official partners WorkBuddy (including CodeBuddy) and OpenCode now fully support V4.1-Flash.
For vibe-coding, the Codeforces rating of 3471 and the DeepSWE v1.1 score of 74.2 put V4.1-Flash at the top of the comparison, ahead of Opus-5.0 and GPT-5.6 Sol. Combined with the low price and 1M context, this makes it a strong default model for coding agents that run long sessions and accumulate large context windows.
Try DeepSeek V4.1-Flash on vega.chat
DeepSeek V4.1-Flash is available now on vega.chat and through the api.vega.chat API. You can test it in the chat interface, compare its responses side by side with other models, or integrate it into your applications via the OpenRouter-compatible API at api.vega.chat.